
Filters and sampling
Decide which traffic an eval scores: filters on any trace field (one agent, spans by name or kind, runs inside a conversation) and sampling to score a steady share. Plus Filter steps inside an eval.
An eval scores every trace of its level unless you narrow it. Traffic that doesn't match costs nothing and makes no result; Analysis counts it under Not scored · did not match the filter.
Filters
Set them on the create page, or later in Settings → Filters. Changing them makes a new version.
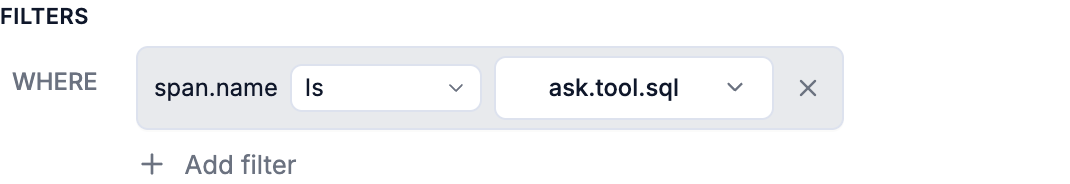
Click + Add filter, search for a property, pick an operator and a value:
| Property type | Operators |
|---|---|
| Text | Is · Is not · Contains · Does not contain · Starts with · Ends with · Matches regex · Is set · Is not set |
| Number | Equals · Not equal · Greater than · Greater than or equal to · Less than · Less than or equal to · Is set · Is not set |
| True / false | Is true · Is false · Is set · Is not set |
Rules in a group are combined with one AND / OR choice for the group.
What you can filter on depends on the level:
| Level | Properties |
|---|---|
| Run | The run's own fields (agent, status, duration, tokens, cost, error), its metadata keys, and Its spans |
| Span | The span's own fields (kind, name, tool, model, status, duration, tokens), its attributes, and its run's fields |
| Conversation | The thread's fields, and Its runs |
One agent
Which agent an eval scores is a filter like any other: Agent name is support-bot. With no agent filter, the eval scores every agent. (The agent name is the name you give wrapAgent.)
Runs that used a certain span
On a run eval, Its spans adds a Spans where … block. Pick Span name or Span kind first to say which span the block is about, then add conditions about that same span:
Spans where Span name is
run_sql· Status iserror
means runs with a run_sql call that errored. The same way, a conversation eval can filter Runs where …, with span blocks inside.
Per-customer evals
Anything you set with run.setMetadata({ tenant, plan }) becomes a filter: metadata.tenant is acme makes an eval for one customer, with its own versions and thresholds. See What evals read.
Sampling
Sampling decides how much of the matching traffic is scored: Every run, or A share you set as a percentage.
- The same traces are chosen every time: a trace is always in or always out of one eval's sample, and lowering the share keeps every trace that was already in.
- Each eval samples independently, so two evals at 10% see different traffic.
- Traces outside the sample cost nothing and are counted under Not scored · outside the sample.
- Sampling changes immediately and never makes a version. Re-scoring history ignores it.
Use sampling to cap cost on high-volume agents, and to keep a Human review step's queue at a size people can keep up with.
Filter steps
A Filter step is a rule inside an eval: the same filter builder, answering true when the trace matches, so a walk can branch on a field without writing Python. Status is error → Fail (errored run); otherwise → the rest of the eval.
Use the eval's filters to decide what is scored; use a Filter step to decide which way a scored trace goes.
Variables: passing data between steps
Declare what a Python step passes on, read it in a later judge as {{steps.step.key}} or in Python as t.steps.step.key, and use what earlier steps answered, with the rule for what a step can read.
Testing and versions
Test an eval on real traces before it scores anything, save versions with notes, set one as production, restore an old one, and re-score history.